Appendix E — Word Embedding
At the core of neural networks is the use of linear algebra to combine feature vectors. Using neural networks for text processing is therefore problematic, as text is a sequence of words and symbols rather than a vector of real numbers.
In this note, we will look at how text can be represented with real-valued word vectors. This transformation is a key step in using machine learning for natural language processing (NLP) and is called encoding or embedding.
The aim of an emdedding is to design a lookup table, where each word can be mapped to a vector.
E.1 One-Hot Encoding
The simplest embedding is the one-hot vector. Each symbol in a dictionary of size n is represented as a vector where all elements are zero, except for a single entry of one at the index corresponding to that word.
Example E.1 (One-Hot Encoding) Consider the following alphabetically sorted dictionary: {a, cat, is, sitting}. The dictionary size is 4, so the word vector sizes are 4 \times 1. The one-hot encodings for cat and sitting could be as follows:
\mathbf{x}_{\mathtt{cat}} = \begin{bmatrix} 0 \\ 1 \\ 0 \\ 0 \end{bmatrix}\,, \quad
\mathbf{x}_{\mathtt{sitting}} = \begin{bmatrix} 0 \\ 0 \\ 0 \\ 1 \end{bmatrix}
The problem with one-hot word vectors is the sheer scale of languages. There are about 200,000 words in current use in the English language, which altogether create about 13 million different tokens. Word vectors generated by one-hot encoding would be embedded in a vector space of dimension 13 million!
In neural networks, this would require input vectors of dimension 13 million and thus would necessitate training an enormous number of weights. We therefore need to find a more compact representation.
Another issue is that one-hot encoding does not capture any semantic relationship between words.
Let’s look at the word vectors we have defined with one-hot. In theory we could add the word vectors as follows:
2 \mathbf{x}_{\mathtt{cat}} + 3.2 \mathbf{x}_{\mathtt{sitting}} - 1.5 \mathbf{x}_{\mathtt{is}}
but we will end up with vectors that are difficult to interpret. For instance, what would be the meaning of
2 \mathbf{x}_{\mathtt{cat}} + 3.2 \mathbf{x}_{\mathtt{sitting}} - 1.5 \mathbf{x}_{\mathtt{is}} = \begin{bmatrix} 0 \\ 2 \\ -1.5 \\ 3.2 \end{bmatrix} = \mathbf{x}_{?}
Also, by definition, for any two distinct dictionary entries \mathbf{x}_1 and \mathbf{x}_2, we have \mathbf{x}_1^{\top}\mathbf{x}_2 = 0. Consequently, their cosine similarity is always zero, regardless of whether the words are synonyms or entirely unrelated.
We require an encoding where words are represented by vectors that makes sense in an Euclidean space: where linear combinations of word vectors and scalar products make as much sense as possible.
E.2 Word2Vec
Word2Vec (2013) was the first neural embedding model to gain widespread popularity, but many competing non-deep learning techniques exist—such as GloVe (Global Vectors for Word Representation), which relies on matrix factorisation of co-occurrence statistics.
Word2Vec proposes two main predictive approaches: Continuous Bag of Words (CBOW), in which the context is used to predict a target word, and Skip-gram, in which the context is predicted from a target word.
Let’s look at the Skip-gram approach, where we take a target word \mathbf{x}_t and attempt to predict its surrounding context words (e.g. \mathbf{x}_{t-2}, \mathbf{x}_{t-1}, \mathbf{x}_{t+1}, \mathbf{x}_{t+2}).

The model follows an encoder-decoder architecture. The input is a one-hot vector of size n, the encoder produces a compact embedding of size r, and the decoder attempts to reconstruct the context word probabilities.

Note that training this model is non trivial as the final softmax layer must handle millions of entries. Calculating the exponentials for such a large dictionary is computationally complex, requiring specialised techniques such as hierarchical softmax or negative sampling.
E.3 Doing Maths with these Embeddings
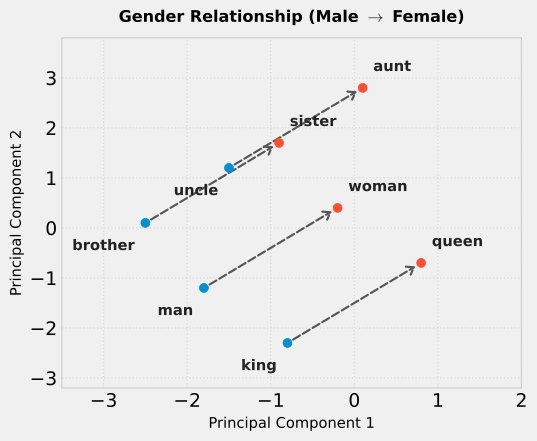
After training, we oberve that the learnt embedding spaces capture semantic and syntactic relationships. Notably we observe linear substructures, which allow for algebraic manipulation of concepts through simple vector arithmetic. A famous example is the gender / royalty relationship demonstrated by Mikolov et al. (2013):
\mathbf{x}_{\text{king}} - \mathbf{x}_{\text{man}} + \mathbf{x}_{\text{woman}} \approx \mathbf{x}_{\text{queen}}
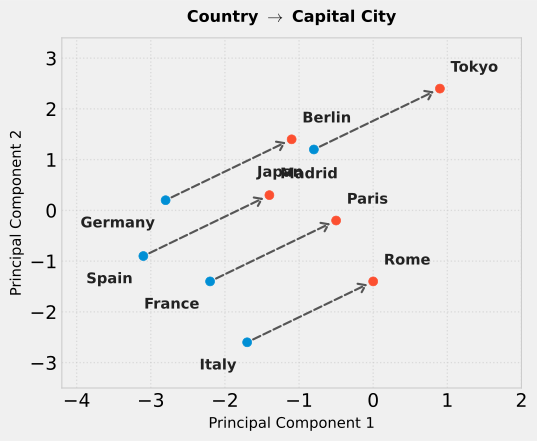
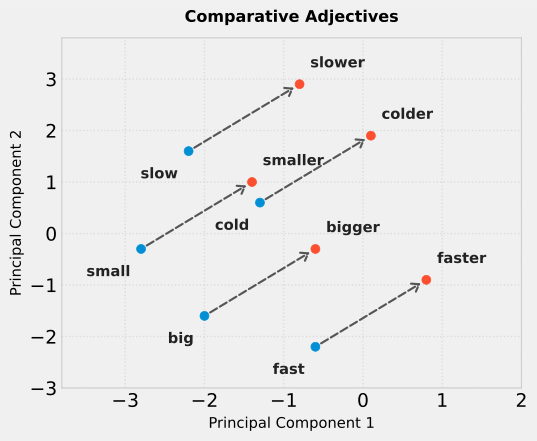
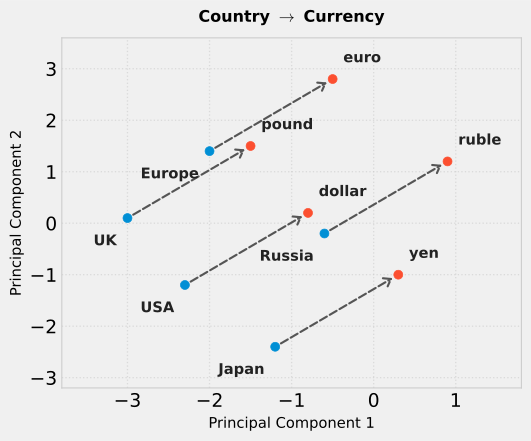
When projected onto a two-dimensional subspace (e.g. via Principal Component Analysis), word pairs sharing the same relationship are connected by approximately parallel translation vectors (Figure E.1).
E.3.1 Additive Compositionality
Similarly Mikolov et al. (2013) discovered that element-wise vector addition acts a bit like a semantic “AND” operator:
| Vector Addition | Closest Tokens in Word2Vec Space |
|---|---|
| \mathbf{x}_{\text{Czech}} + \mathbf{x}_{\text{currency}} | koruna, Czech crown, Polish zloty |
| \mathbf{x}_{\text{Vietnam}} + \mathbf{x}_{\text{capital}} | Hanoi, Ho Chi Minh City, Vietnamese |
| \mathbf{x}_{\text{German}} + \mathbf{x}_{\text{airlines}} | Lufthansa, airline, German Airways |
| \mathbf{x}_{\text{Russian}} + \mathbf{x}_{\text{river}} | Volga River, upriver, Dnieper |
E.3.2 Nearest Neighbours and Semantic Similarity
These embeddings are equally effective at capturing semantic proximity using the cosine similarity (scalar product between normalized vectors):
\text{similarity}(\mathbf{u}, \mathbf{v}) = \frac{\mathbf{u}^{\top} \mathbf{v}}{\|\mathbf{u}\| \, \|\mathbf{v}\|}
For instance, computing the nearest neighbours to the query word "frog" in the pre-trained Google News Word2Vec model yields closely related amphibians and biological variants:
"frog" in the word2vec-google-news-300 vector space.
| Rank | Nearest Neighbour | Cosine Similarity |
|---|---|---|
| 1 | frogs |
0.80 |
| 2 | toad |
0.79 |
| 3 | bullfrog |
0.73 |
| 4 | tree_frog |
0.70 |
| 5 | toads |
0.69 |
You can explore Word2Vec embeddings, test analogies, and create your own 2D projection plots directly in Google Colab: 
E.4 Tokenisation: Beyond Word-Level Embeddings
While word-level embeddings like Word2Vec and GloVe show that text can be meaningfully mapped into a Euclidean space, they suffer from several significant limitations:
- Out-of-Dictionary (OOD) Problem: If a model encounters a word that was not in its training vocabulary (e.g. a typo, a new technical term, or a rare name), it cannot generate a vector for it.
- Morphology: They treat different forms of the same root word (e.g. “walk”, “walking”, “walked”) as entirely distinct.
Modern Large Language Models (LLMs) solve these issues by using tokenisation instead of simple word-level encoding. Techniques such as Byte-Pair Encoding (BPE) or WordPiece breakdown words into frequent groups of bytes or sub-word units.
In this approach, common words might remain as single tokens, but rare words are decomposed into smaller, more frequent sub-units. For example, the word “unhappily” might be broken down into un + happi + ly.
This offers a bridge between character-level and word-level encoding:
- Like character-level encoding, it can represent any arbitrary string by breaking it down into its constituent parts (even down to individual bytes), thus eliminating the out-of-dictionary problem.
- Like word-level encoding, it retains semantic meaning in its tokens, as frequent sub-words (like prefixes and suffixes) carry consistent information across different contexts.
E.4.1 Do LLM Tokens Exhibit Similar Linear Substructures?
Do we observe similar linear relationships among tokens in modern Large Language Models (LLMs)? The short answer is no, not at the token embedding level.
This is because partly because tokens are often morphological fragments (such as " un", "token", or "ization"). Summing subword embeddings does not produce the embedding of the compound word.
Linear sub sturctures are, however, found in the depth of the LLM. Mechanistic interpretability research has shown that linear structure migrates from the input token table into the residual stream, the layer-by-layer communication bus that connects all Transformer blocks:
The Linear Representation Hypothesis (LRH) is that high-level human-interpretable concepts (such as factual truthfulness, sentiment, gender, grammatical tense, or language) are encoded as linear directions or subspaces within the model’s intermediate residual stream activations.
Just as Word2Vec added a vector offset to shift meaning, modern practitioners can perform representation engineering by adding a constant steering vector \mathbf{v}_{\text{concept}} directly into the residual stream at test time (\mathbf{x}_l \leftarrow \mathbf{x}_l + \alpha \mathbf{v}), predictably shifting the model’s tone, reasoning, or honesty without fine-tuning weights.
Thus, while token embeddings themselves no longer behave like Word2Vec words, the fundamental geometric intuition—that meaning can be organised along linear directions—remains central to how deep networks reason.
E.5 Further Reading
For those wishing to explore word embeddings, tokenisation, and representation geometry in more detail, you can look at the following resources:
- Efficient Estimation of Word Representations in Vector Space, T. Mikolov, K. Chen, G. Corrado, and J. Dean (2013).
- GloVe: Global Vectors for Word Representation, J. Pennington, R. Socher, and C. Manning (2014).
- Neural Machine Translation of Rare Words with Subword Units, R. Sennrich, B. Haddow, and A. Birch (2015) — the foundational paper for BPE in NLP.
- A Mathematical Framework for Transformer Circuits, C. Elhage et al. (2021) — formalises the residual stream as a communication bus.
- The Geometry of Truth: Emergent Linear Structure in Large Language Model Representations of True/False Datasets, S. Marks and M. Tegmark (2023).
- The Linear Representation Hypothesis and the Geometry of Concepts, K. Park et al. (2023).